Model Emergence
Variational Neural Inference: an executable tutorial
Eleven notebooks that run from tensors and gradients to sequential VAEs and interpretable nonlinear dynamics, a walkthrough of the models, the figures they produce, and what each one adds.
Most introductions to variational inference either stop at the ELBO or jump straight to a published model with ten thousand lines of scaffolding. This tutorial is my attempt at the path between the two: eleven notebooks that build from gradients and latent variables to sequential VAEs on spike trains, where every step runs and every model is small enough to read.
It grew out of teaching material for our lab. It assumes you know Python but not necessarily PyTorch, and that you care about neural data specifically, the examples are spikes, posture, and latent dynamics rather than MNIST digits.
The notebooks live on GitHub: msenselab/Variational-Neural-Inference. What follows is a walkthrough of where they go and what each stage buys you. Every figure below is real output from the notebook it names, click any of them to open the full-size version.
The progression
gradients
    -> latent variables
    -> mixture models and EM
    -> temporal states and dynamic programming
    -> amortized variational inference
    -> recurrent neural dynamics
    -> nonlinear but locally interpretable dynamics
Each step adds exactly one idea, and each notebook is where that idea is made to work on data.
1. Gradients, before anything else
The first two notebooks exist so that nobody has to pretend they already know PyTorch. Tensors, autograd, a loss surface, and a network small enough that every weight can be drawn on the page.
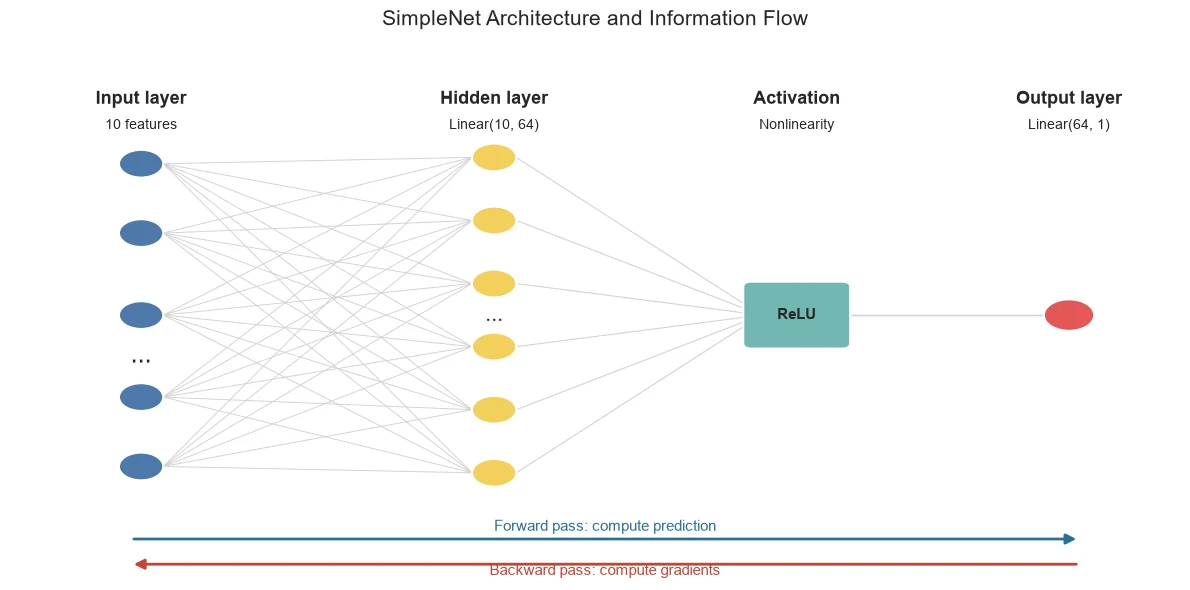
01_pytorch_neuroscience_introduction.ipynbBy the end of this part you have fitted a GLM to neural responses by gradient descent. That is the whole toolkit the later models are built from.
2. Latent variables, and the algorithm that finds them
A mixture model is the smallest interesting model with something hidden in it: the data are observed, the cluster label is not. Fitting it by EM is where the ELBO first appears, and it appears as something you derive rather than something you are handed.
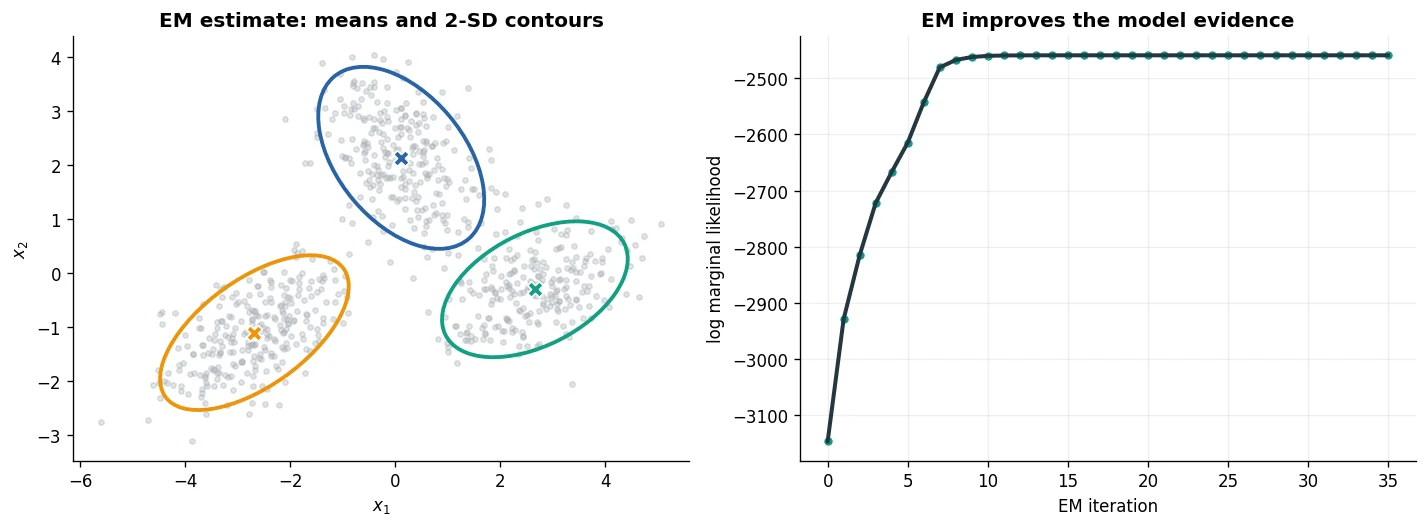
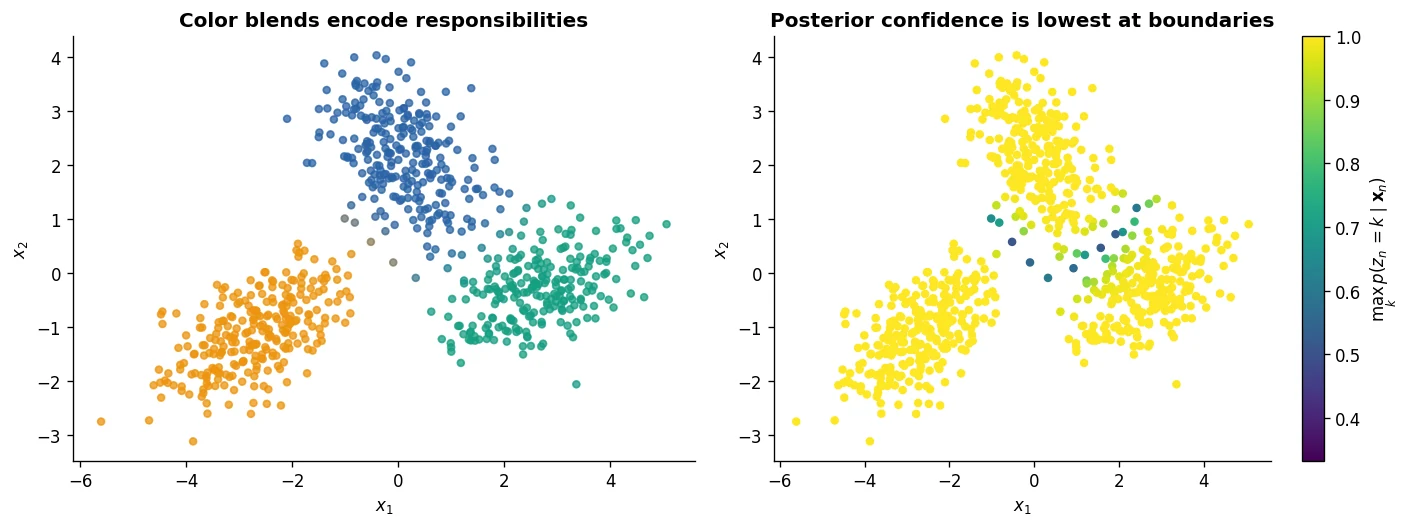
02b_mixtures_em.ipynbThe part worth slowing down for is what the E step actually produces. Not a label per point, a distribution over labels, which is soft exactly where the data are ambiguous.
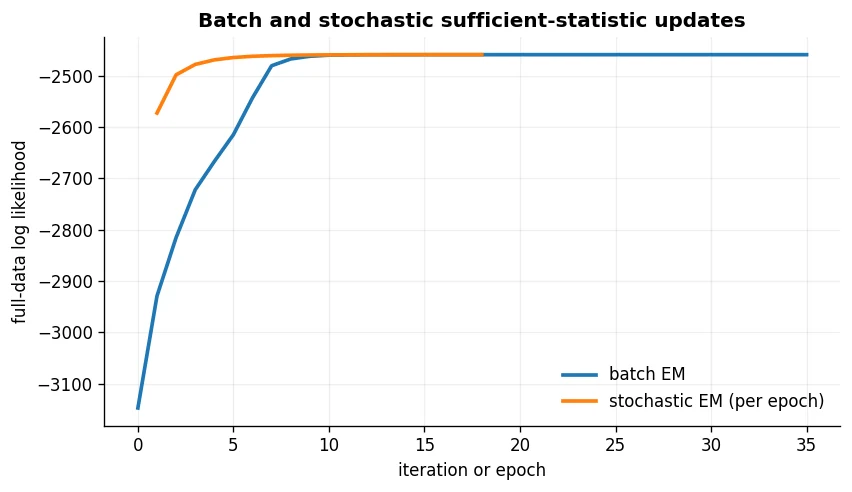
02b_mixtures_em.ipynbThe same notebook ends with stochastic EM, which is the first hint that these algorithms survive being run on minibatches, the thing that will later make amortized inference practical.
02b_mixtures_em.ipynb3. Adding time
An HMM is a mixture model whose hidden label is allowed to persist. That single change buys dynamic programming: forward-backward, smoothing, Viterbi decoding, Baum-Welch.
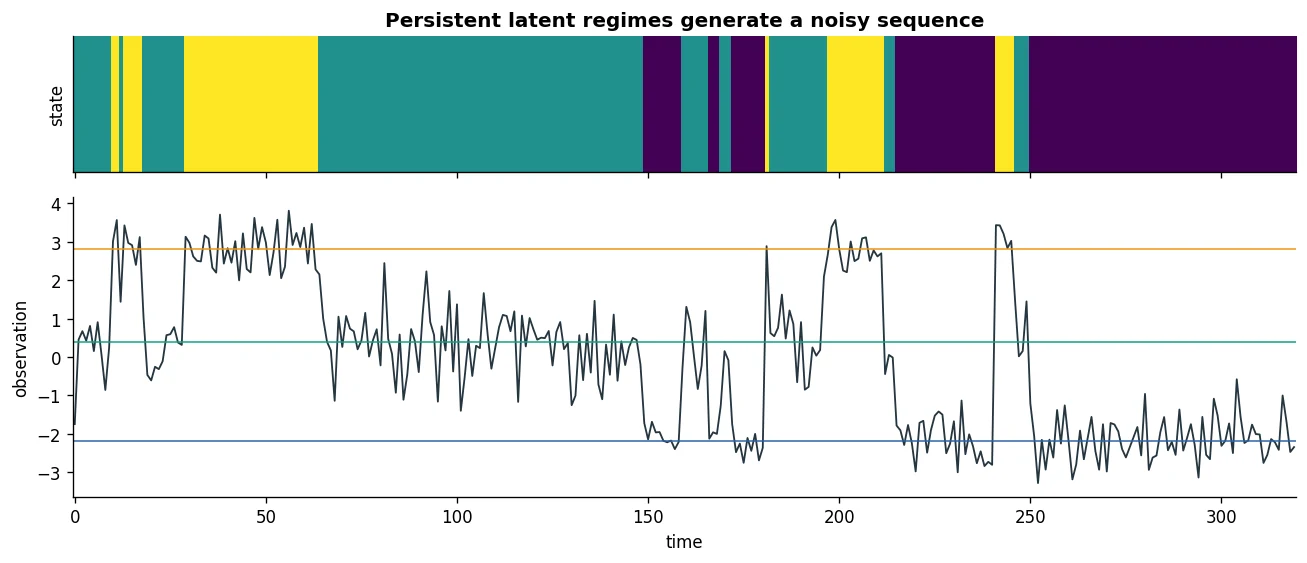
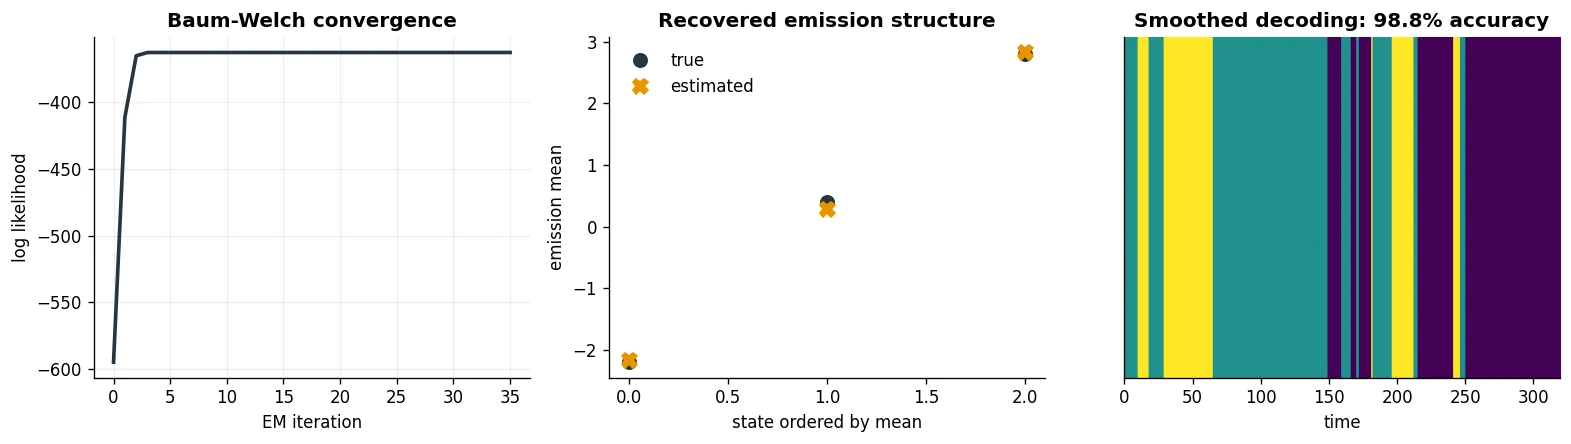
03a_hmm_foundations.ipynbAnd it is recoverable. Running Baum-Welch on that sequence recovers the emission parameters and decodes the state path at 98.8% accuracy, from the observations alone.
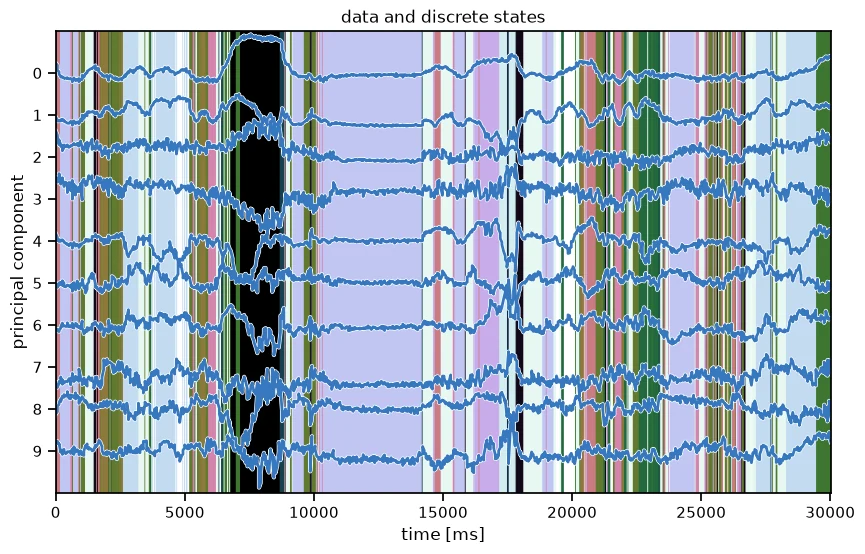
03a_hmm_foundations.ipynbThe extended workshop takes the same machinery to real behavioural recordings, where an AR-HMM segments continuous posture dynamics into discrete, recurring syllables.
03_hmm_lds.ipynb4. The VAE, and what amortization actually means
Everything so far computed a posterior by running an algorithm per data point. The VAE’s move is to train a network to predict the posterior instead, one forward pass, any data point, including ones never seen during fitting.
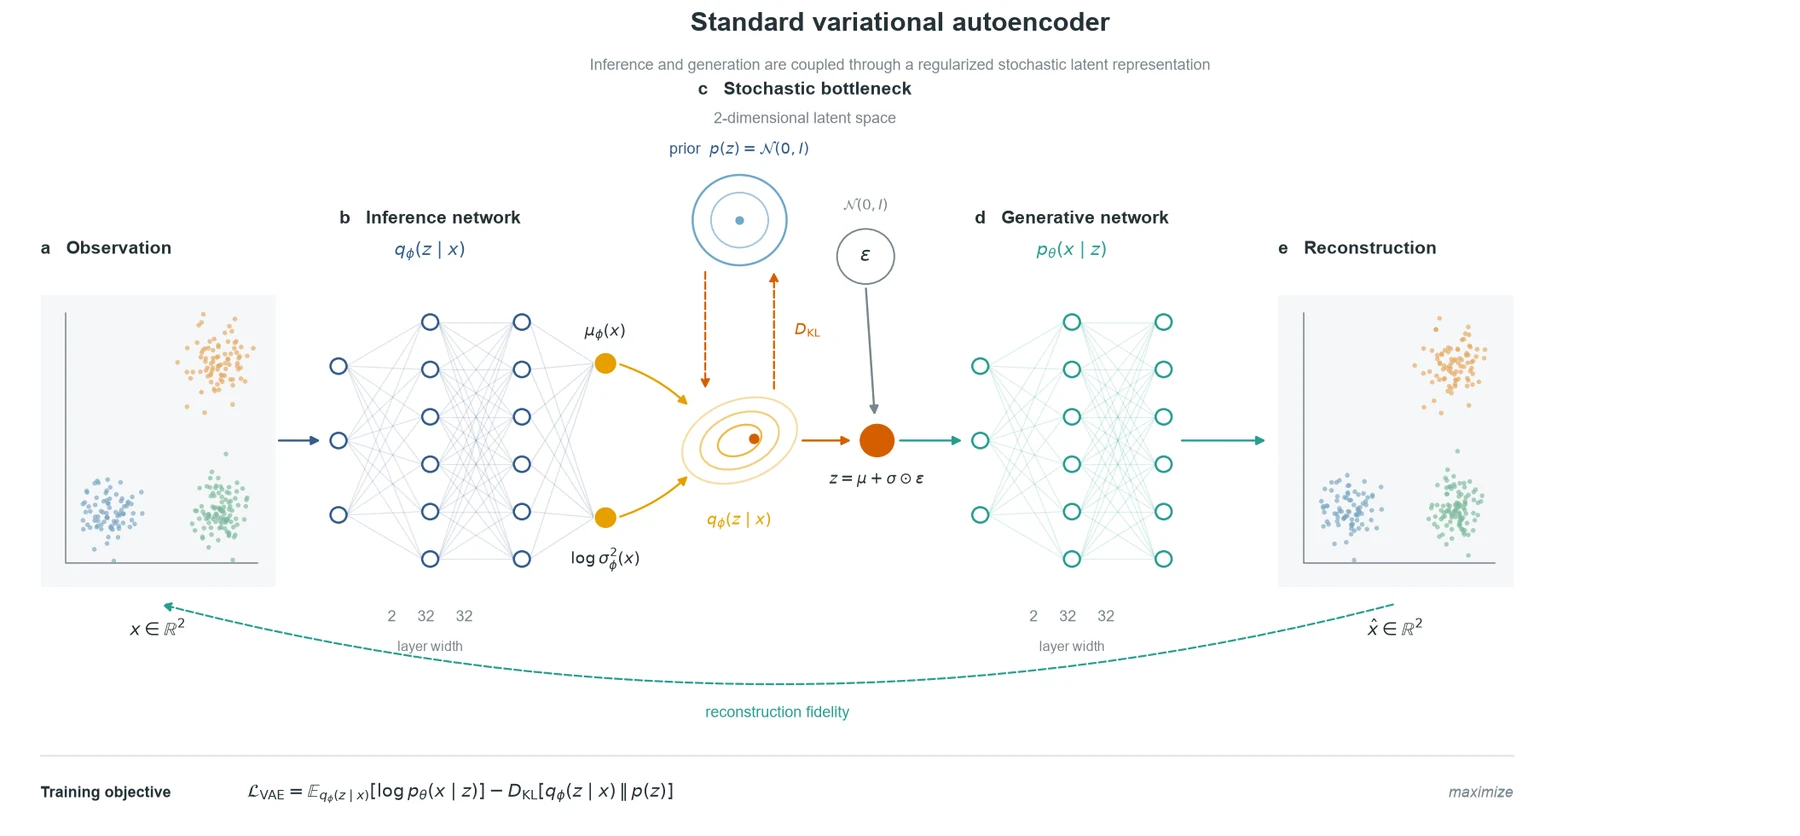
04_standard_vae.ipynbTraining it on clustered data shows what the latent space is for: structure that was spread across the observation space gets folded into two dimensions, with the clusters still separated.
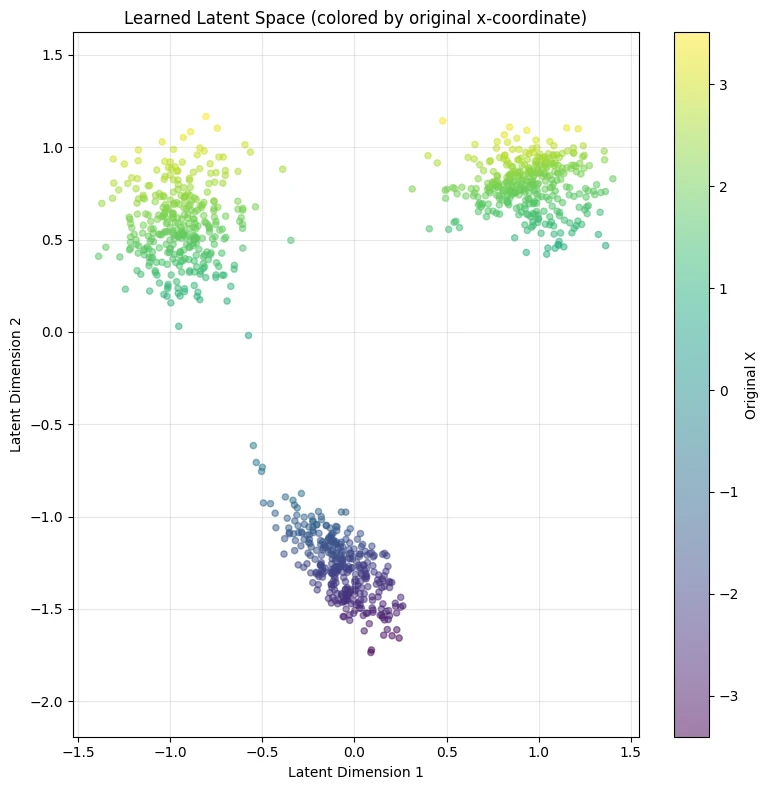
04_standard_vae.ipynbIf you have read about VAEs and still do not feel you could write one, this is the notebook I would hand you.
5. Doing the inference by hand
Before trusting a network to produce posteriors, it is worth deriving them once. Notebook 05 does coordinate-ascent variational inference and variational EM explicitly, then turns the result on the Kato et al. whole-brain recordings and asks whether the inferred discrete states mean anything.
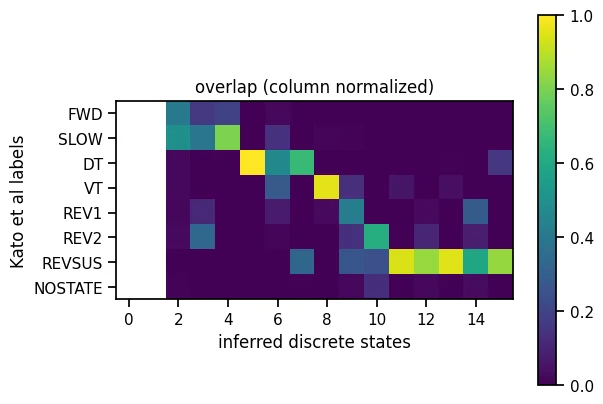
05_variational_em.ipynb6. Dynamics: the sequential VAE
LFADS is where the two halves meet. The latent variable becomes the state of a recurrent generator, inference becomes a bidirectional encoder over the whole trial, and the observation model becomes Poisson spikes.
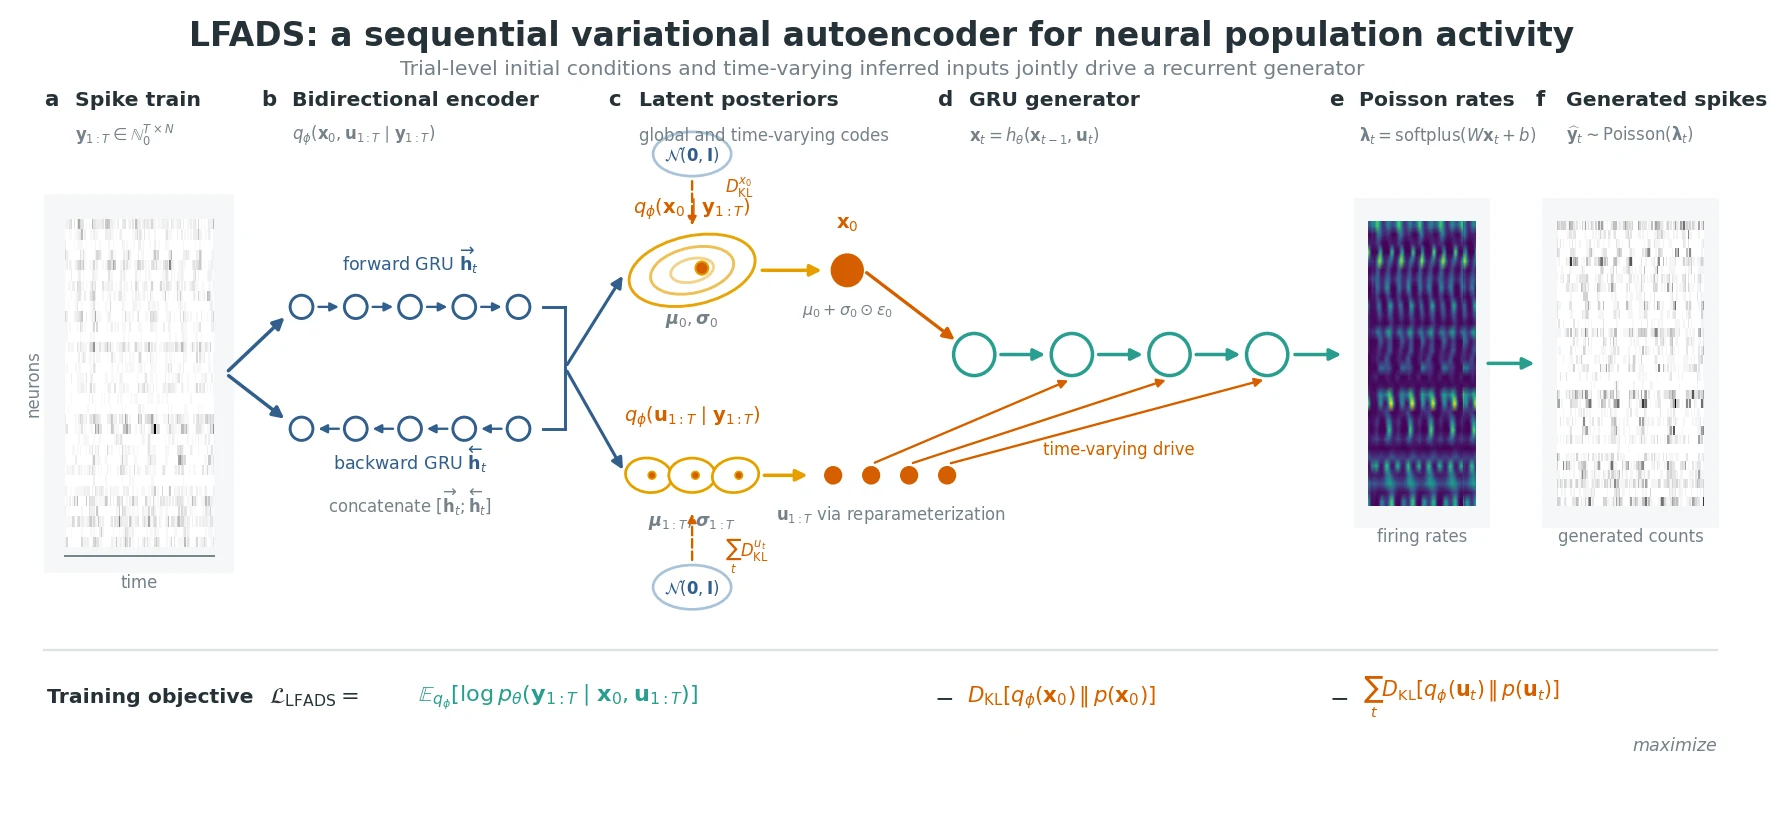
06_lfads.ipynbBecause the data are synthetic here, the learned dynamics can be checked against the oscillator that actually produced them, including a Lyapunov estimate and a phase portrait of the learned autonomous system.
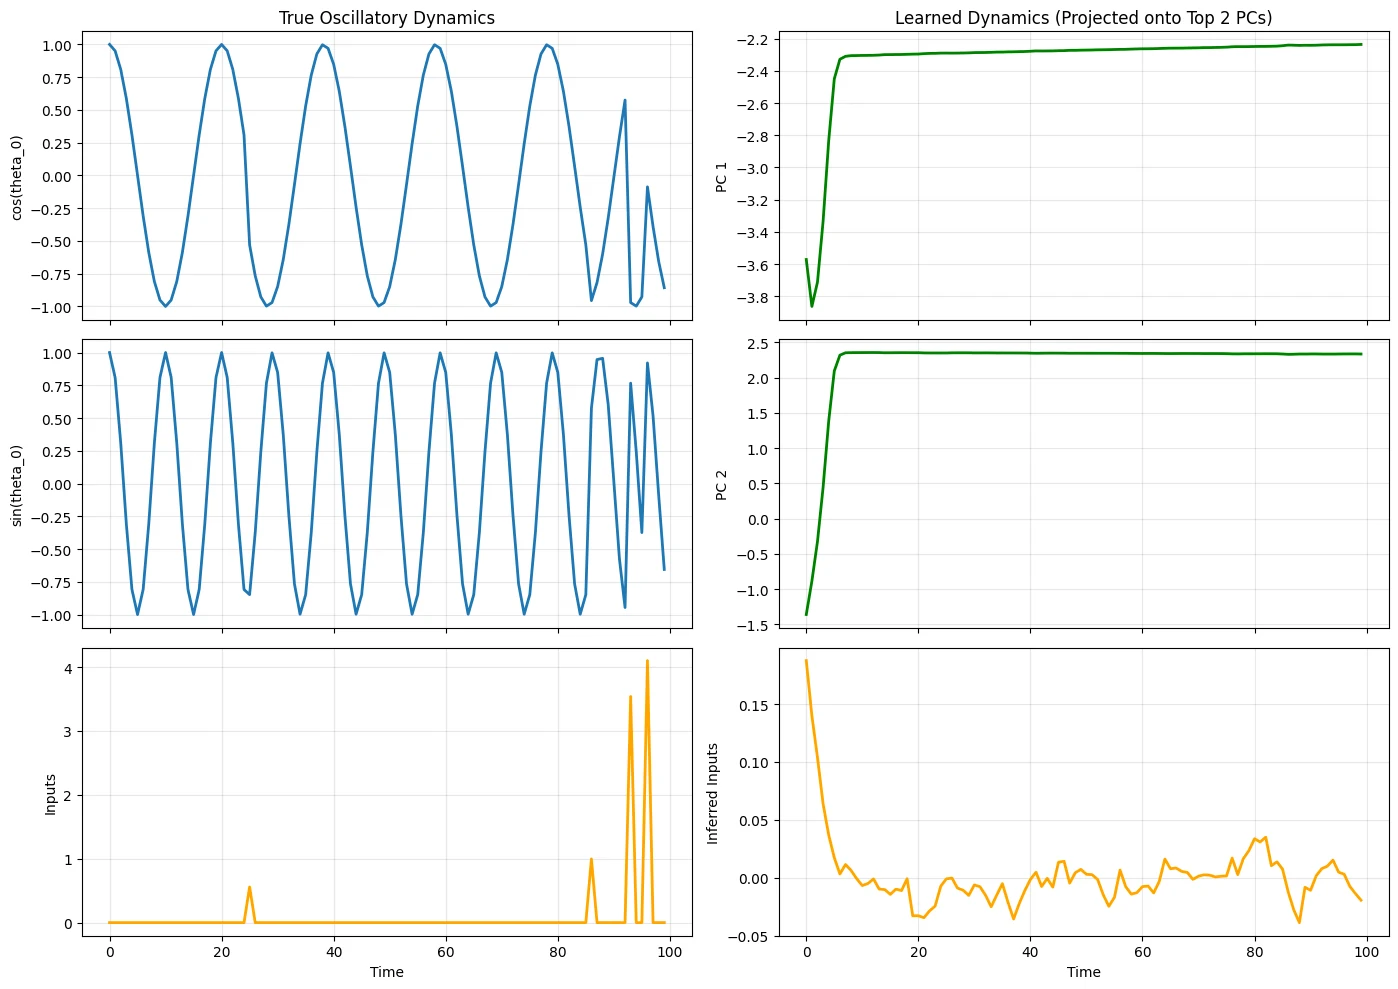
06_lfads.ipynb7. Nonlinear, but still interpretable
A recurrent generator is expressive and opaque. gpSLDS is the capstone because it gives up some of that expressiveness on purpose: the vector field is a Gaussian process built from locally linear regimes, so the fitted dynamics can still be read.
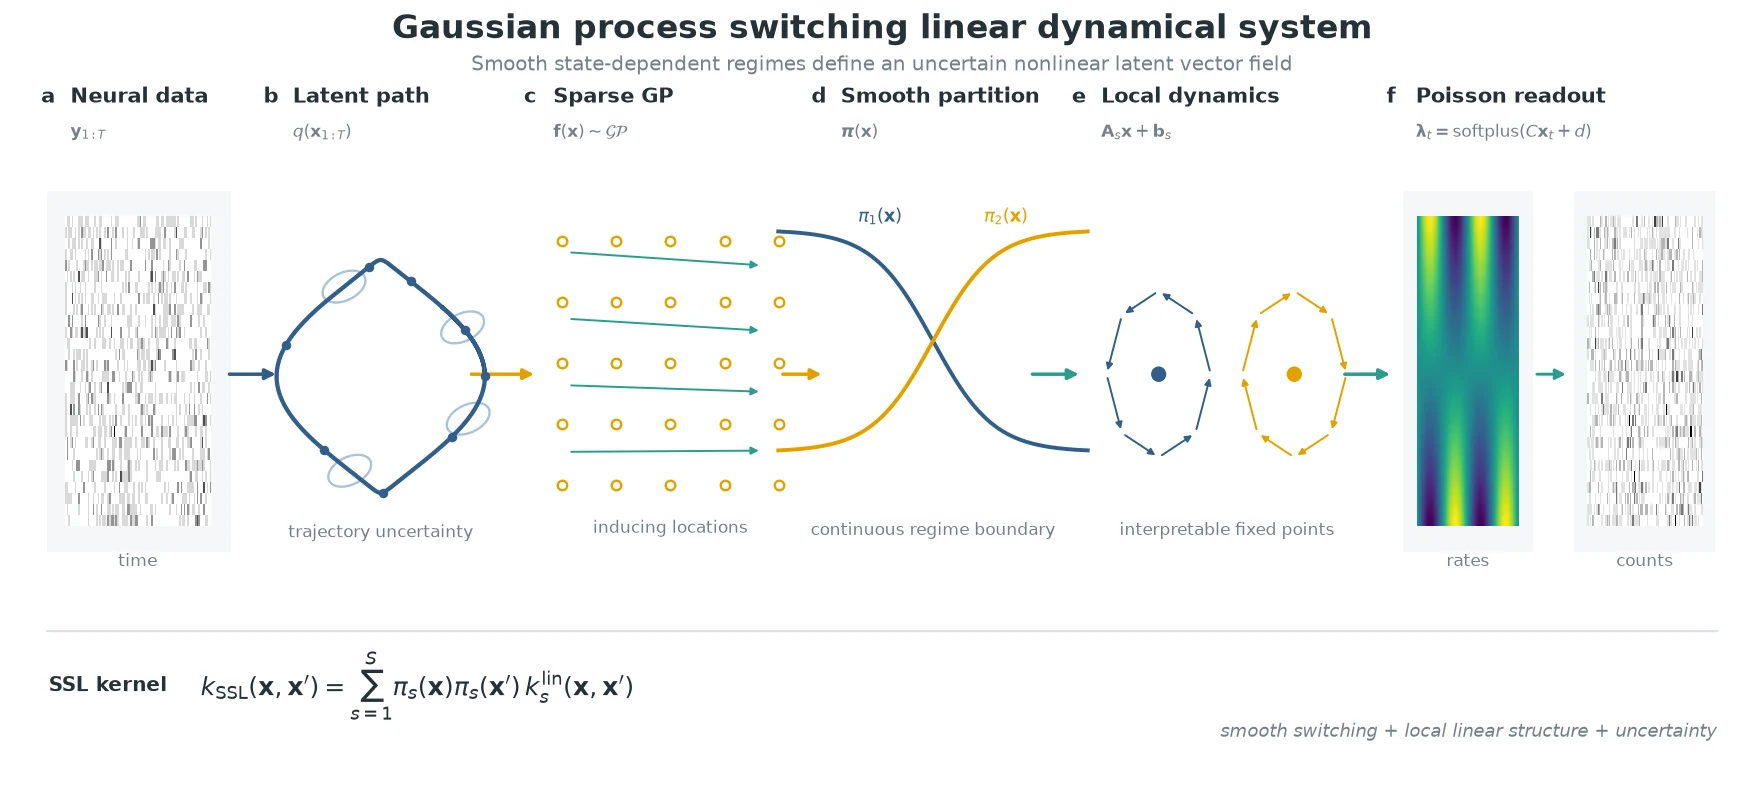
08_gpslds.ipynb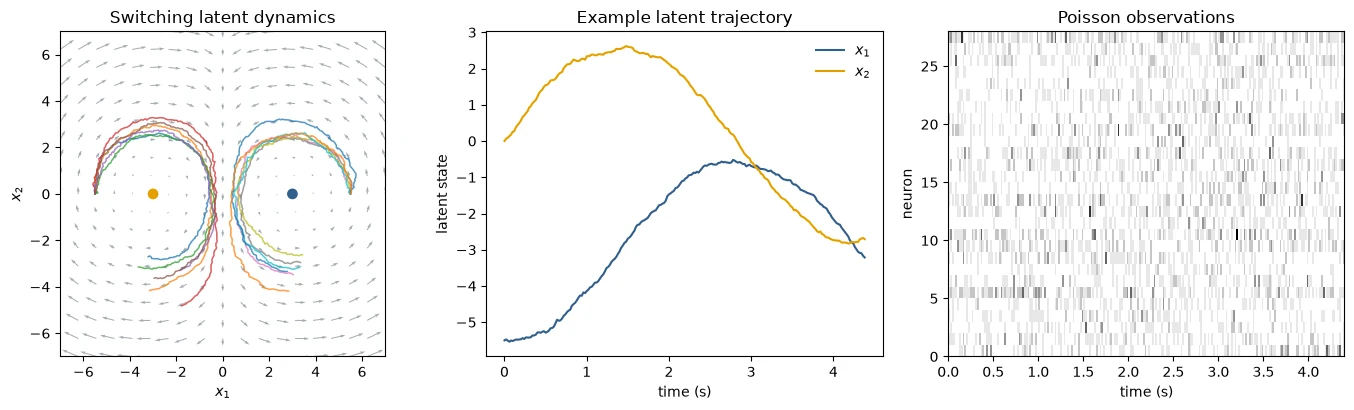
08_gpslds.ipynb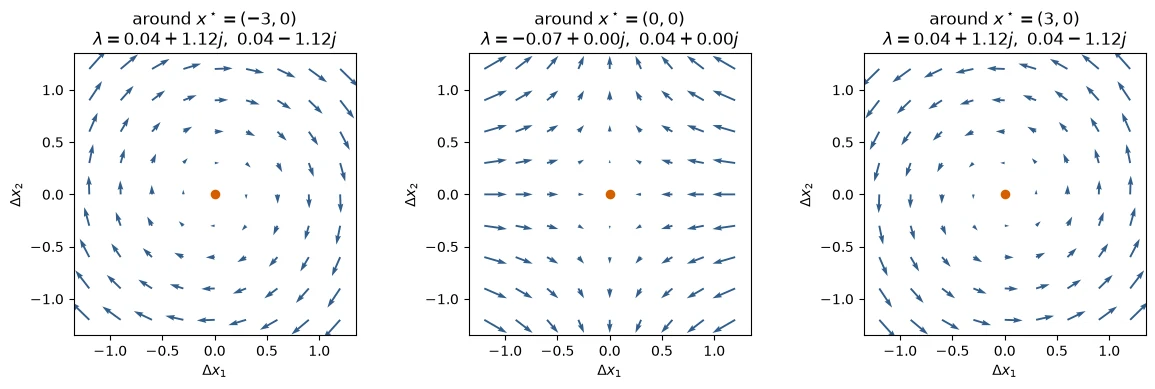
08_gpslds.ipynbAll eleven notebooks
| # | Notebook | What it covers |
|---|---|---|
| 00 | PyTorch Primer | Exercise-based PyTorch primer |
| 01 | PyTorch for Neuroscience | Visual introduction, seminar prerequisite |
| 02 | Probabilistic Modeling | Probability and latent-variable foundations |
| 02b | Mixture Models and EM | Mixtures, EM, the ELBO, stochastic EM |
| 03a | HMM Foundations | Forward-backward, decoding, sampling, Baum-Welch |
| 03 | From Behaviour to Latent Dynamics | Gaussian and AR-HMM extended workshop |
| 04 | Standard VAE | The ELBO and amortized inference |
| 05 | Variational EM | CAVI and coordinate-ascent variational EM |
| 06 | Sequential VAEs (LFADS) | Transparent PyTorch LFADS for spike trains |
| 07 | Advanced LFADS Reference | Full JAX workflow, inferring inputs to an integrator RNN |
| 08 | gpSLDS | Interpretable nonlinear dynamics, conceptual capstone |
If you read four of them, read 02, 04, 06 and 08. Notebooks 00 and 01 are prerequisites rather than lessons, and the complete classical inference track is 02 → 02b → 03a.
Running them
Notebooks 07 and 08 depend on external implementations registered as Git submodules, so downloading single files is not enough for those two:
git clone https://github.com/msenselab/Variational-Neural-Inference.git
cd Variational-Neural-Inference
python scripts/setup_all.py
The setup script initializes the submodules, applies the JAX and NumPy
compatibility patches, and installs a CPU-compatible environment for all eleven
notebooks. It is idempotent, and --dry-run shows what it would do. For a
smaller install, requirements-core.txt covers notebooks 00-06.
Where the notebooks are honest about their limits, so is this page: notebook 05 runs its full synthetic CAVI tutorial without any download and only fetches the Kato dataset if you opt in; notebook 06 splits 950 training and 50 genuinely held-out test trials; notebook 08 demonstrates the gpSLDS computational core rather than reproducing the full upstream fitting pipeline.
Attribution
The tutorial adapts material from Stanford’s
STATS 320 and from the original model
implementations; references/ATTRIBUTION.md in the repository has the details.
The underlying papers are Kingma and Welling (2013) for the VAE, Pandarinath et
al. (2018) for LFADS, Vyas et al. (2020) for computation through dynamics, and
Hu et al. (2024) for gpSLDS.